

Associate-Cloud-Engineer Dumps PDF - Associate-Cloud-Engineer Real Exam Questions Answers
Get Started: Associate-Cloud-Engineer Exam [2021] Dumps Google PDF Questions
Google Associate Cloud Engineer Exam
An associated cloud engineer distributes applications, monitors operations and manages business solutions. This person can use the Google Cloud Console and the command-line interface to perform common platform-based activities to maintain one or more distributed solutions that take advantage of services managed or self-managed by Google in Google Cloud
The Google Cloud Certification Program offers Google Cloud users, customers and partners a way to demonstrate their technical skills in a specific role or technology. People are evaluated using a variety of rigorously developed standard methods to determine if they meet Google Cloud competition standards. The cost of certification exams varies. if you do not pass an exam, you can repeat it after 14 days. If you do not take it a second time, you must wait 60 days before you can take it a third time. If it fails a third time, you must wait a year before resuming it. You can try the test in several languages, but each attempt, regardless of language, counts the total number of attempts allowed and the waiting period between attempts remains valid. Payment is required each time an exam is taken. Avoiding this recovery policy by registering with a different name or any other means constitutes a violation of the terms and conditions of the exam and will result in the denial or revocation of a certification. Exams are designed to determine only if a person meets a minimum standard of approval or not. They are not meant to be diagnostic or spread people on a capacity scale. For this reason, numerical scores are not significant for the candidate and can be misunderstood. Google Cloud Certification Program recognizes that some other exam providers provide section comments on their exams. Google doesnât do it because it makes no sense and could be misleading. Google Cloud Certification tests are not designed to diagnose strengths and weaknesses. Google Cloud Certification exam sections are very broad categories of topics, and the range of specific questions that can be received for each section in a single exam session is extremely small in comparison. Based on such a small amount of data, there are no significant comments at the section level that we can provide responsibly. We follow the procedures accepted by the industry to ensure that our exams are valid and accurate. Our exam development process includes the following steps: A task analysis (JTA) is a formal study that begins with the identification of role representatives, technology experts and stakeholders. These experts are interviewed and interviewed in a seminar to obtain information about what people do in a particular job or role and what skills distinguish the skills. These skills are defined in the exam guides that we write on the web. Our question authors are subject matter experts who worked in the certified role. The question editors are trained in the exam standards and conventions that we apply to our exams. All questions are examined to determine if they meet the standards and are technically accurate. Once the questions have passed all warnings and approvals, they are published in a beta test. The purpose of the beta exam is to collect performance statistics related to the exam questions to determine which ones are the most effective. We review the statistics and comments on the questions and eliminate questions that do not meet our standards. The minimum score for each exam is reserved. It is determined by a group of internal and external experts in the field, following a process of setting standards accepted by the sector. The minimum score applies equally to all candidates. It is reevaluated when changes are made to the content of the exam. The delivery method for an exam depends on its format.
NEW QUESTION 81
You deployed a new application inside your Google Kubernetes Engine cluster using the YAML file specified below.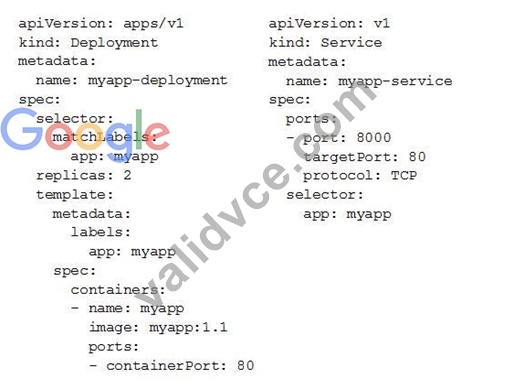
You check the status of the deployed pods and notice that one of them is still in PENDING status: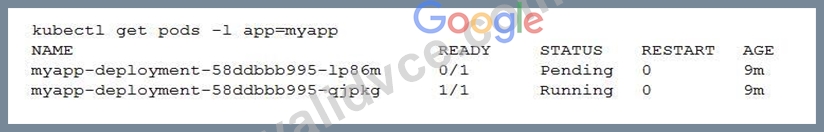
You want to find out why the pod is stuck in pending status. What should you do?
- A. View logs of the container in myapp-deployment-58ddbbb995-lp86m pod and check for warning messages.
- B. Review details of the myapp-service Service object and check for error messages.
- C. Review details of myapp-deployment-58ddbbb995-lp86m Pod and check for warning messages.
- D. Review details of the myapp-deployment Deployment object and check for error messages.
Answer: C
NEW QUESTION 82
You're attempting to deploy a new instance that uses the centos 7 family. You can't recall the exact name of the family. Which command could you use to determine the family names?
- A. gcloud compute images show-families
- B. gcloud compute images list
- C. gcloud compute instances list
- D. gcloud compute instances show-families
Answer: A,B
NEW QUESTION 83
You manage an App Engine Service that aggregates and visualizes data from BigQuery. The application is deployed with the default App Engine Service account. The data that needs to be visualized resides in a different project managed by another team. You do not have access to this project, but you want your application to be able to read data from the BigQuery dataset. What should you do?
- A. In Cloud IAM of your project, grant a newly created service account from the other team the role of BigQuery Job User in your project.
:
The Owner, Editor, and Viewer primitive roles include the BigQuery Admin (roles/bigquery.dataOwner), BigQuery Data Editor (roles/bigquery.dataEditor), and BigQuery Data Viewer (roles/bigquery.dataViewer) roles, respectively. This means the Owner, Editor, and Viewer primitive roles have BigQuery access as defined for the respective BigQuery roles. - B. Ask the other team to grant your default App Engine Service account the role of BigQuery Data Viewer.
- C. Ask the other team to grant your default App Engine Service account the role of BigQuery Job User.
- D. In Cloud IAM of your project, ensure that the default App Engine service account has the role of BigQuery Data Viewer.
Answer: D
Explanation:
Reference:
https://cloud.google.com/bigquery/docs/access-control
NEW QUESTION 84
Your company implemented BigQuery as an enterprise data warehouse. Users from multiple business units run queries on this data warehouse. However, you notice that query costs for BigQuery are very high, and you need to control costs. Which two methods should you use? (Choose two.)
- A. Change your BigQuery query model from on-demand to flat rate. Apply the appropriate number of slots to each Project.
- B. Create separate copies of your BigQuery data warehouse for each business unit.
- C. Split the users from business units to multiple projects.
- D. Apply a user- or project-level custom query quota for BigQuery data warehouse.
- E. Split your BigQuery data warehouse into multiple data warehouses for each business unit.
Answer: A,D
NEW QUESTION 85
You are configuring service accounts for an application that spans multiple projects. Virtual machines (VMs) running in the web-applications project need access to BigQuery datasets in crm-databases-proj. You want to follow Google-recommended practices to give access to the service account in the web-applications project. What should you do?
- A. Give "project owner" role to crm-databases-proj and the web-applications project.
- B. Give "project owner" role to crm-databases-proj and bigquery.dataViewer role to web-applications.
- C. Give "project owner" for web-applications appropriate roles to crm-databases- proj
- D. Give bigquery.dataViewer role to crm-databases-proj and appropriate roles to web-applications.
Answer: D
Explanation:
Reference:
https://cloud.google.com/blog/products/gcp/best-practices-for-working-with-google-cloud-audit- logging
NEW QUESTION 86
Your development team needs a new Jenkins server for their project. You need to deploy the server using the fewest steps possible. What should you do?
- A. Create a Kubernetes cluster on Compute Engine and create a deployment with the Jenkins Docker image.
- B. Create a new Compute Engine instance and install Jenkins through the command line interface.
- C. Use GCP Marketplace to launch the Jenkins solution.
- D. Download and deploy the Jenkins Java WAR to App Engine Standard.
Answer: C
Explanation:
Explanation/Reference: https://cloud.google.com/solutions/using-jenkins-for-distributed-builds-on-compute-engine
NEW QUESTION 87
You are developing a new application and are looking for a Jenkins installation to build and deploy your source code. You want to automate the installation as quickly and easily as possible. What should you do?
- A. Create an instance template with the Jenkins executable. Create a managed instance group with this template.
- B. Create a new Compute Engine instance. Run the Jenkins executable.
- C. Deploy Jenkins through the Google Cloud Marketplace.
- D. Create a new Kubernetes Engine cluster. Create a deployment for the Jenkins image.
Answer: C
Explanation:
Reference:
https://cloud.google.com/solutions/jenkins-on-kubernetes-engine
NEW QUESTION 88
You need to create an autoscaling managed instance group for an HTTPS web application. You want to make sure that unhealthy VMs are recreated. What should you do?
- A. Select Multi-Zone instead of Single-Zone when creating the Managed Instance Group.
- B. Create a health check on port 443 and use that when creating the Managed Instance Group.
- C. In the Instance Template, add the label `health-check'.
- D. In the Instance Template, add a startup script that sends a heartbeat to the metadata server.
Answer: C
NEW QUESTION 89
You have a Linux VM that must connect to Cloud SQL. You created a service account with the appropriate access rights. You want to make sure that the VM uses this service account instead of the default Compute Engine service account. What should you do?
- A. Download a JSON Private Key for the service account. On the Custom Metadata of the VM, add that JSON as the value for the key compute-engine-service-account.
- B. When creating the VM via the web console, specify the service account under the 'Identity and API Access' section.
- C. Download a JSON Private Key for the service account. After creating the VM, ssh into the VM and save the JSON under ~/.gcloud/compute-engine-service-account.json.
- D. Download a JSON Private Key for the service account. On the Project Metadata, add that JSON as the value for the key compute-engine-service-account.
Answer: B
Explanation:
Explanation/Reference: https://cloud.google.com/compute/docs/access/create-enable-service-accounts-for-instances
NEW QUESTION 90
You have successfully created a development environment in a project for an application. This application uses Compute Engine and Cloud SQL. Now, you need to create a production environment for this application. The security team has forbidden the existence of network routes between these 2 environments, and asks you to follow Google-recommended practices. What should you do?
- A. Create a new production subnet in the existing VPC and a new production Cloud SQL instance in your existing project, and deploy your application using those resources.
- B. Create a new project, enable the Compute Engine and Cloud SQL APIs in that project, and replicate the setup you have created in the development environment.
- C. Create a new project, modify your existing VPC to be a Shared VPC, share that VPC with your new project, and replicate the setup you have in the development environment in that new project, in the Shared VPC.
- D. Ask the security team to grant you the Project Editor role in an existing production project used by another division of your company. Once they grant you that role, replicate the setup you have in the development environment in that project.
Answer: B
NEW QUESTION 91
You want to configure a solution for archiving data in a Cloud Storage bucket. The solution must be cost-effective. Data with multiple versions should be archived after 30 days. Previous versions are accessed once a month for reporting. This archive data is also occasionally updated at month-end. What should you do?
- A. Add a bucket lifecycle rule that archives data from regional storage after 30 days to Nearline Storage.
- B. Add a bucket lifecycle rule that archives data from regional storage after 30 days to Coldline Storage.
- C. Add a bucket lifecycle rule that archives data with newer versions after 30 days to Nearline Storage.
- D. Add a bucket lifecycle rule that archives data with newer versions after 30 days to Coldline Storage.
Answer: C
Explanation:
Reference:
https://cloud.google.com/storage/docs/managing-lifecycles
NEW QUESTION 92
You are running an application on multiple virtual machines within a managed instance group and have autoscaling enabled. The autoscaling policy is configured so that additional instances are added to the group if the CPU utilization of instances goes above 80%. VMs are added until the instance group reaches its maximum limit of five VMs or until CPU utilization of instances lowers to 80%. The initial delay for HTTP health checks against the instances is set to 30 seconds. The virtual machine instances take around three minutes to become available for users. You observe that when the instance group autoscales, it adds more instances then necessary to support the levels of end-user traffic. You want to properly maintain instance group sizes when autoscaling. What should you do?
- A. Set the maximum number of instances to 1.
- B. Use a TCP health check instead of an HTTP health check.
- C. Increase the initial delay of the HTTP health check to 200 seconds.
- D. Decrease the maximum number of instances to 3.
Answer: C
NEW QUESTION 93
You are running multiple VPC-native Google Kubernetes Engine clusters in the same subnet. The IPs available for the nodes are exhausted, and you want to ensure that the clusters can grow in nodes when needed. What should you do?
- A. Add an alias IP range to the subnet used by the GKE clusters.
- B. Create a new subnet in the same region as the subnet being used.
- C. Create a new VPC, and set up VPC peering with the existing VPC.
- D. Expand the CIDR range of the relevant subnet for the cluster.
Answer: D
NEW QUESTION 94
You are building a pipeline to process time-series dat
a. Which Google Cloud Platform services should you put in boxes 1,2,3, and 4?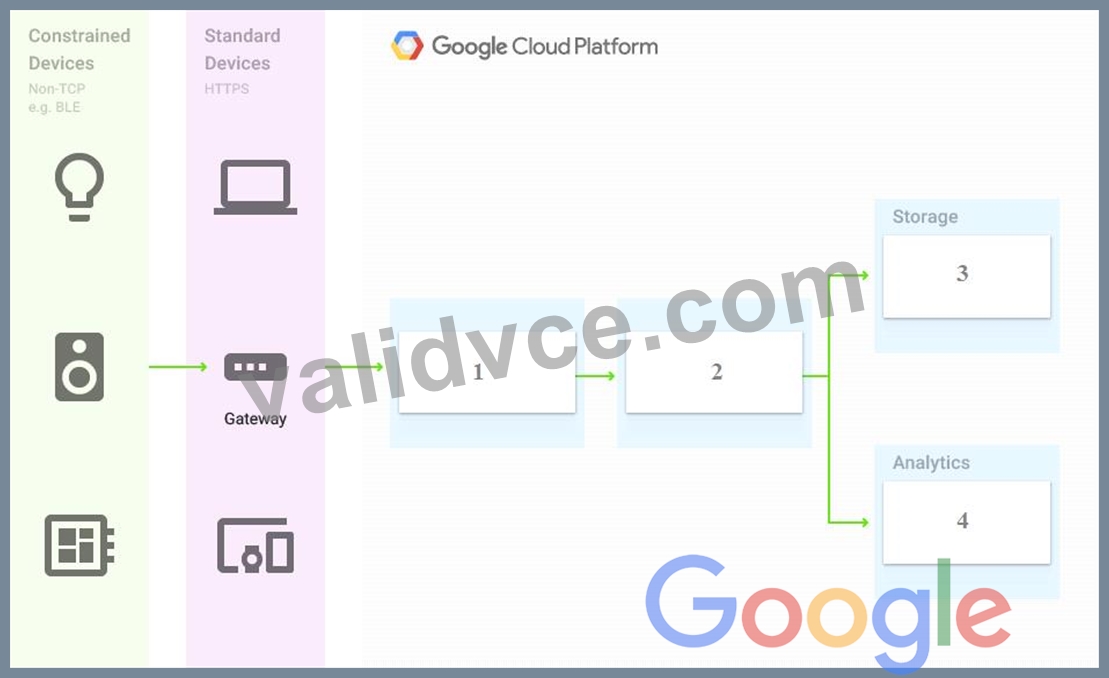
- A. Firebase Messages, Cloud Pub/Sub, Cloud Spanner, BigQuery
- B. Cloud Pub/Sub, Cloud Dataflow, Cloud Bigtable, BigQuery
- C. Cloud Pub/Sub, Cloud Storage, BigQuery, Cloud Bigtable
- D. Cloud Pub/Sub, Cloud Dataflow, Cloud Datastore, BigQuery
Answer: B
NEW QUESTION 95
You want to run a single caching HTTP reverse proxy on GCP for a latency-sensitive website. This specific reverse proxy consumes almost no CPU. You want to have a 30-GB in-memory cache, and need an additional 2 GB of memory for the rest of the processes. You want to minimize cost. How should you run this reverse proxy?
- A. Run it on Compute Engine, and choose a custom instance type with 6 vCPUs and 32 GB of memory.
- B. Create a Cloud Memorystore for Redis instance with 32-GB capacity.
- C. Run it on Compute Engine, choose the instance type n1-standard-1, and add an SSD persistent disk of 32 GB.
- D. Package it in a container image, and run it on Kubernetes Engine, using n1-standard-32 instances as nodes.
Answer: A
NEW QUESTION 96
For analysis purposes, you need to send all the logs from all of your Compute Engine instances to a BigQuery dataset called platform-logs. You have already installed the Stackdriver Logging agent on all the instances.
You want to minimize cost. What should you do?
- A. 1. In Stackdriver Logging, create a logs export with a Cloud Pub/Sub topic called logs as a sink.2.
Create a Cloud Function that is triggered by messages in the logs topic.3. Configure that Cloud Function to drop logs that are not from Compute Engine and to insert Compute Engine logs in the platform-logs dataset. - B. 1. In Stackdriver Logging, create a filter to view only Compute Engine logs.2. Click Create Export.3.
Choose BigQuery as Sink Service, and the platform-logs dataset as Sink Destination. - C. 1. Create a Cloud Function that has the BigQuery User role on the platform-logs dataset.2. Configure this Cloud Function to create a BigQuery Job that executes this query:INSERT INTO dataset.platform-logs (timestamp, log)SELECT timestamp, log FROM compute.logsWHERE timestamp
> DATE_SUB(CURRENT_DATE(), INTERVAL 1 DAY)3. Use Cloud Scheduler to trigger this Cloud Function once a day. - D. 1. Give the BigQuery Data Editor role on the platform-logs dataset to the service accounts used by your instances.2. Update your instances' metadata to add the following value: logs-destination:
bq://platform-logs.
Answer: B
NEW QUESTION 97
You have a web application deployed as a managed instance group. You have a new version of the application to gradually deploy. Your web application is currently receiving live web traffic.
You want to ensure that the available capacity does not decrease during the deployment. What should you do?
- A. Perform a rolling-action start-update with maxSurge set to 1 and maxUnavailable set to 0.
- B. Create a new managed instance group with an updated instance template.
Add the group to the backend service for the load balancer.
When all instances in the new managed instance group are healthy, delete the old managed instance group. - C. Create a new instance template with the new application version.
Update the existing managed instance group with the new instance template.
Delete the instances in the managed instance group to allow the managed instance group to recreate the instance using the new instance template. - D. Perform a rolling-action start-update with maxSurge set to 0 and maxUnavailable set to 1.
Answer: B
NEW QUESTION 98
......
Associate-Cloud-Engineer Premium Exam Engine pdf Download: https://www.validvce.com/Associate-Cloud-Engineer-exam-collection.html
Verified Associate-Cloud-Engineer Bundle Real Exam Dumps PDF: https://drive.google.com/open?id=1m52AD7e-2bmXlJHLm0Eb0yhGhdJcfk-M
