

[Jan-2024] Verified Databricks Databricks-Certified-Data-Engineer-Associate Bundle Real Exam Dumps PDF
Databricks-Certified-Data-Engineer-Associate Dumps PDF New [2024] Ultimate Study Guide
The GAQM Databricks-Certified-Data-Engineer-Associate (Databricks Certified Data Engineer Associate) Certification Exam is a professional certification program designed to assess the skills and knowledge of individuals working in the field of data engineering. Databricks Certified Data Engineer Associate Exam certification validates the ability of data engineers to design, build, and maintain data pipelines and data warehouses using Databricks technologies. Databricks-Certified-Data-Engineer-Associate exam covers a wide range of topics, including data ingestion, data transformation, data modeling, data warehousing, and data quality.
NEW QUESTION # 53
A data engineer has a single-task Job that runs each morning before they begin working. After identifying an upstream data issue, they need to set up another task to run a new notebook prior to the original task.
Which of the following approaches can the data engineer use to set up the new task?
- A. They can clone the existing task in the existing Job and update it to run the new notebook.
- B. They can clone the existing task to a new Job and then edit it to run the new notebook.
- C. They can create a new task in the existing Job and then add it as a dependency of the original task.
- D. They can create a new task in the existing Job and then add the original task as a dependency of the new task.
- E. They can create a new job from scratch and add both tasks to run concurrently.
Answer: B
NEW QUESTION # 54
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.
The code block used by the data engineer is below:
If the data engineer only wants the query to process all of the available data in as many batches as required, which of the following lines of code should the data engineer use to fill in the blank?
- A. trigger(availableNow=True)
- B. trigger(parallelBatch=True)
- C. trigger(processingTime="once")
- D. trigger(continuous="once")
- E. processingTime(1)
Answer: A
Explanation:
Explanation
https://stackoverflow.com/questions/71061809/trigger-availablenow-for-delta-source-streaming-queries-in-pyspa
NEW QUESTION # 55
A data engineer needs to apply custom logic to identify employees with more than 5 years of experience in array column employees in table stores. The custom logic should create a new column exp_employees that is an array of all of the employees with more than 5 years of experience for each row. In order to apply this custom logic at scale, the data engineer wants to use the FILTER higher-order function.
Which of the following code blocks successfully completes this task?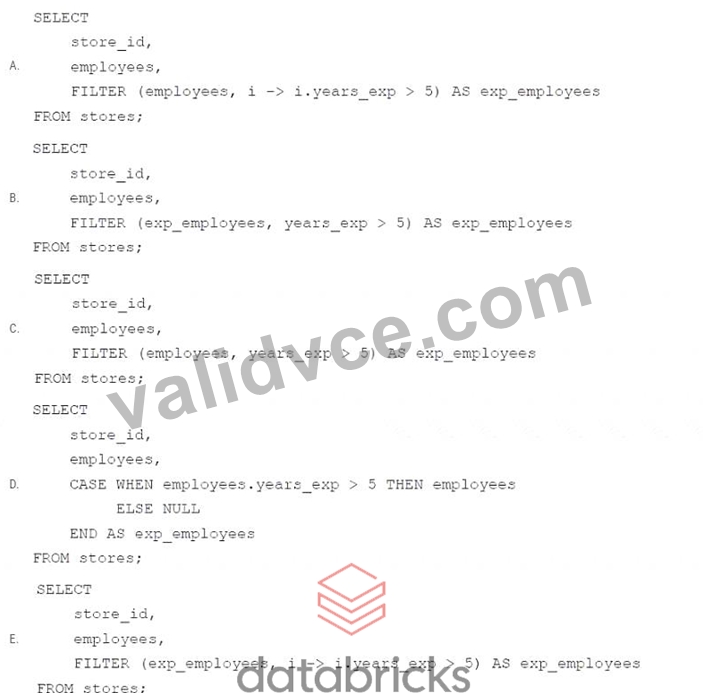
- A. Option B
- B. Option E
- C. Option D
- D. Option C
- E. Option A
Answer: E
NEW QUESTION # 56
A data engineer only wants to execute the final block of a Python program if the Python variable day_of_week is equal to 1 and the Python variable review_period is True.
Which of the following control flow statements should the data engineer use to begin this conditionally executed code block?
- A. if day_of_week = 1 and review_period:
- B. if day_of_week = 1 & review_period: = "True":
- C. if day_of_week == 1 and review_period == "True":
- D. if day_of_week = 1 and review_period = "True":
- E. if day_of_week == 1 and review_period:
Answer: E
Explanation:
Explanation
This statement will check if the variable day_of_week is equal to 1 and if the variable review_period evaluates to a truthy value. The use of the double equal sign (==) in the comparison of day_of_week is important, as a single equal sign (=) would be used to assign a value to the variable instead of checking its value. The use of a single ampersand (&) instead of the keyword and is not valid syntax in Python. The use of quotes around True in options B and C will result in a string comparison, which will not evaluate to True even if the value of review_period is True.
NEW QUESTION # 57
Which of the following describes the relationship between Gold tables and Silver tables?
- A. Gold tables are more likely to contain more data than Silver tables.
- B. Gold tables are more likely to contain valuable data than Silver tables.
- C. Gold tables are more likely to contain truthful data than Silver tables.
- D. Gold tables are more likely to contain a less refined view of data than Silver tables.
- E. Gold tables are more likely to contain aggregations than Silver tables.
Answer: D
NEW QUESTION # 58
A data engineer needs to create a table in Databricks using data from their organization's existing SQLite database.
They run the following command: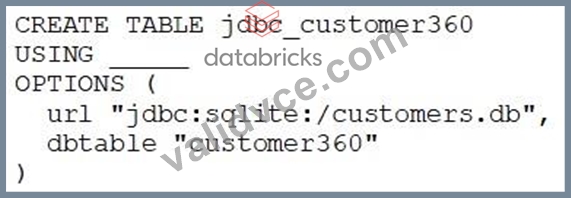
Which of the following lines of code fills in the above blank to successfully complete the task?
- A. org.apache.spark.sql.sqlite
- B. autoloader
- C. sqlite
- D. org.apache.spark.sql.jdbc
- E. DELTA
Answer: D
Explanation:
Explanation
CREATE TABLE new_employees_table
USING JDBC
OPTIONS (
url "<jdbc_url>",
dbtable "<table_name>",
user '<username>',
password '<password>'
) AS
SELECT * FROM employees_table_vw
https://docs.databricks.com/external-data/jdbc.html#language-sql
NEW QUESTION # 59
An engineering manager wants to monitor the performance of a recent project using a Databricks SQL query.
For the first week following the project's release, the manager wants the query results to be updated every minute. However, the manager is concerned that the compute resources used for the query will be left running and cost the organization a lot of money beyond the first week of the project's release.
Which of the following approaches can the engineering team use to ensure the query does not cost the organization any money beyond the first week of the project's release?
- A. They can set the query's refresh schedule to end after a certain number of refreshes.
- B. They cannot ensure the query does not cost the organization money beyond the first week of the project's release.
- C. They can set a limit to the number of DBUs that are consumed by the SQL Endpoint.
- D. They can set the query's refresh schedule to end on a certain date in the query scheduler.
- E. They can set a limit to the number of individuals that are able to manage the query's refresh schedule.
Answer: D
Explanation:
Explanation
If a dashboard is configured for automatic updates, it has a Scheduled button at the top, rather than a Schedule button. To stop automatically updating the dashboard and remove its subscriptions:
Click Scheduled.
In the Refresh every drop-down, select Never.
Click Save. The Scheduled button label changes to Schedule.
Source:https://learn.microsoft.com/en-us/azure/databricks/sql/user/dashboards/
NEW QUESTION # 60
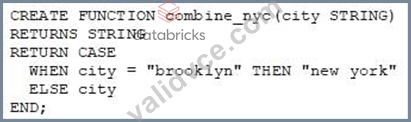
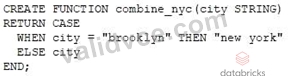
A data engineer needs to apply custom logic to string column city in table stores for a specific use case. In order to apply this custom logic at scale, the data engineer wants to create a SQL user-defined function (UDF).
Which of the following code blocks creates this SQL UDF?
- A.
- B.
- C.
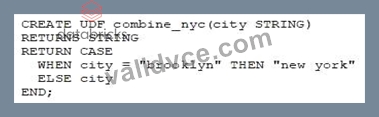
- D.
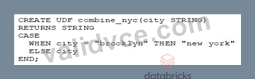
- E.
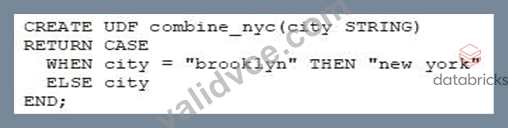
Answer: A
Explanation:
Explanation
https://www.databricks.com/blog/2021/10/20/introducing-sql-user-defined-functions.html
NEW QUESTION # 61
A data engineer has a Job with multiple tasks that runs nightly. Each of the tasks runs slowly because the clusters take a long time to start.
Which of the following actions can the data engineer perform to improve the start up time for the clusters used for the Job?
- A. They can use jobs clusters instead of all-purpose clusters
- B. They can configure the clusters to autoscale for larger data sizes
- C. They can configure the clusters to be single-node
- D. They can use clusters that are from a cluster pool
- E. They can use endpoints available in Databricks SQL
Answer: D
Explanation:
Explanation
Cluster pools are a way to pre-provision clusters that are ready to use. This can reduce the start up time for clusters, as they do not have to be created from scratch. All-purpose clusters are not pre-provisioned, so they will take longer to start up. Jobs clusters are a type of cluster pool, but they are not the best option for this use case. Jobs clusters are designed for long-running jobs, and they can be more expensive than other types of cluster pools. Single-node clusters are the smallest type of cluster, and they will start up the fastest. However, they may not be powerful enough to run the Job's tasks. Autoscaling clusters can scale up or down based on demand. This can help to improve the start up time for clusters, as they will only be created when they are needed. However, autoscaling clusters can also be more expensive than other types of cluster pool
https://docs.databricks.com/en/clusters/pool-best-practices.html
NEW QUESTION # 62
A data engineer is running code in a Databricks Repo that is cloned from a central Git repository. A colleague of the data engineer informs them that changes have been made and synced to the central Git repository. The data engineer now needs to sync their Databricks Repo to get the changes from the central Git repository.
Which of the following Git operations does the data engineer need to run to accomplish this task?
- A. Push
- B. Pull
- C. Clone
- D. Merge
- E. Commit
Answer: B
Explanation:
Explanation
From the docs:
In Databricks Repos, you can use Git functionality to:
Clone, push to, and pull from a remote Git repository.
Create and manage branches for development work, including merging, rebasing, and resolving conflicts.
Create notebooks—including IPYNB notebooks—and edit them and other files.
Visually compare differences upon commit and resolve merge conflicts.
Source: https://docs.databricks.com/en/repos/index.html
NEW QUESTION # 63
Which of the following benefits is provided by the array functions from Spark SQL?
- A. An ability to work with complex, nested data ingested from JSON files
- B. An ability to work with data within certain partitions and windows
- C. An ability to work with time-related data in specified intervals
- D. An ability to work with data in a variety of types at once
- E. An ability to work with an array of tables for procedural automation
Answer: A
Explanation:
Explanation
Array functions in Spark SQL are primarily used for working with arrays and complex, nested data structures, such as those often encountered when ingesting JSON files. These functions allow you to manipulate and query nested arrays and structures within your data, making it easier to extract and work with specific elements or values within complex data formats. While some of the other options (such as option A for working with different data types) are features of Spark SQL or SQL in general, array functions specifically excel at handling complex, nested data structures like those found in JSON files.
NEW QUESTION # 64
A data engineer has left the organization. The data team needs to transfer ownership of the data engineer's Delta tables to a new data engineer. The new data engineer is the lead engineer on the data team.
Assuming the original data engineer no longer has access, which of the following individuals must be the one to transfer ownership of the Delta tables in Data Explorer?
- A. This transfer is not possible
- B. Original data engineer
- C. Databricks account representative
- D. New lead data engineer
- E. Workspace administrator
Answer: E
Explanation:
Explanation
https://docs.databricks.com/sql/admin/transfer-ownership.html
NEW QUESTION # 65
Which of the following data lakehouse features results in improved data quality over a traditional data lake?
- A. A data lakehouse allows the use of SQL queries to examine data.
- B. A data lakehouse supports ACID-compliant transactions.
- C. A data lakehouse provides storage solutions for structured and unstructured data.
- D. A data lakehouse enables machine learning and artificial Intelligence workloads.
- E. A data lakehouse stores data in open formats.
Answer: B
Explanation:
Explanation
One of the key features of a data lakehouse that results in improved data quality over a traditional data lake is its support for ACID (Atomicity, Consistency, Isolation, Durability) transactions. ACID transactions provide data integrity and consistency guarantees, ensuring that operations on the data are reliable and that data is not left in an inconsistent state due to failures or concurrent access. In a traditional data lake, such transactional guarantees are often lacking, making it challenging to maintain data quality, especially in scenarios involving multiple data writes, updates, or complex transformations. A data lakehouse, by offering ACID compliance, helps maintain data quality by providing strong consistency and reliability, which is crucial for data pipelines and analytics.
NEW QUESTION # 66
A Delta Live Table pipeline includes two datasets defined using STREAMING LIVE TABLE. Three datasets are defined against Delta Lake table sources using LIVE TABLE.
The table is configured to run in Production mode using the Continuous Pipeline Mode.
Assuming previously unprocessed data exists and all definitions are valid, what is the expected outcome after clicking Start to update the pipeline?
- A. All datasets will be updated at set intervals until the pipeline is shut down. The compute resources will be deployed for the update and terminated when the pipeline is stopped.
- B. All datasets will be updated once and the pipeline will persist without any processing. The compute resources will persist but go unused.
- C. All datasets will be updated once and the pipeline will shut down. The compute resources will be terminated.
- D. All datasets will be updated once and the pipeline will shut down. The compute resources will persist to allow for additional testing.
- E. All datasets will be updated at set intervals until the pipeline is shut down. The compute resources will persist to allow for additional testing.
Answer: D
NEW QUESTION # 67
A data engineer needs to apply custom logic to string column city in table stores for a specific use case. In order to apply this custom logic at scale, the data engineer wants to create a SQL user-defined function (UDF).
Which of the following code blocks creates this SQL UDF?
- A.
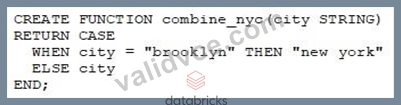
- B.
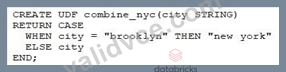
- C.
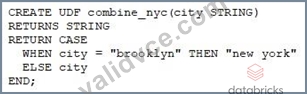
- D.
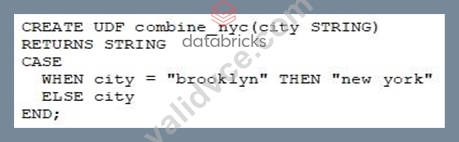
- E.
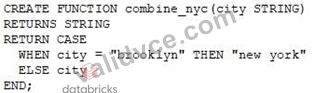
Answer: C
NEW QUESTION # 68
......
The GAQM Databricks-Certified-Data-Engineer-Associate certification is an essential credential for individuals and organizations working with big data using Databricks. It validates the candidate's skills and knowledge of data engineering concepts and their ability to design and implement data pipelines using Databricks. Databricks Certified Data Engineer Associate Exam certification is globally recognized and highly respected in the industry, making it a valuable asset for anyone looking to advance their career in the field of data engineering.
Pass Your Databricks Exam with Databricks-Certified-Data-Engineer-Associate Exam Dumps: https://www.validvce.com/Databricks-Certified-Data-Engineer-Associate-exam-collection.html
Databricks-Certified-Data-Engineer-Associate Exam Dumps PDF Updated Dump: https://drive.google.com/open?id=1OJMwTqGXTPnrdMmzUWaOWP38zwA0qjNm
